Cohere Labs Open Science Community

Benchmark Radar

Keeping a Living Map of AI Evaluation
Koutian Wu · M.A. candidate in AI for Sciences, UT Austin
Koutian Wu*, Wenjun Zhang*, Junjie Zhou, Pengqian Han, Qiming Bao, Ergan Shang, Jiayu Wang, Junkai Wang, Wanghan Xu, Songyuanyi Lu, Yixuan Li, Rudy Mizrahi Celekli, Lazizbek Ravshanov, Yaoliang Bian, Xudong Han, Lin Shi
*Equal contribution to the paper and the code.
benchmark-radar.org · ktwu@utexas.edu
Where it started

Before you build an eval: has anyone measured this already?

  • The answers are scattered. arXiv, GitHub, dataset pages, model cards, technical reports, leaderboards.
  • A name is only the start. What does it measure? Is the code still up? Who reported scores, and under which prompt, tools, and attempts?
  • And the pile keeps growing: 2,940 new benchmark releases in 90 days.
Lin Shi, a core contributor to harbor-framework and Terminal-Bench, advised us and helped bring this work about.
2,940 = releases in Benchmark Radar's 90-day window, retrieved Nov 13, 2026 (scripts/release_repo_findings.py).
A real case

Credit assignment: 225 leads, 2 papers

  • Ask.Jiayu Wang planned an eval and asked: does it duplicate August 2026 work on credit assignment in agentic training, with small Qwen baselines?
  • Search.A coding agent installed the Radar Skill and ran several topic variants.
  • Judge.Opening each paper left SRPO and HindSearch: August, credit assignment, small Qwen backbone, released code.
Matches 225
Matched every query word 47
Dated August 2026 38
Met all four conditions 2
Radar finds the candidates and the evidence. The researcher judges what is relevant.
Worked use case contributed by Jiayu Wang, Benchmark Radar technical report.
The project

What Benchmark Radar is

52,120
benchmark records collected
41
public sources, crawled daily
400+
GitHub stars
300+
users
  • Every record keeps its original source and its score history.
  • Open: code on GitHub (pipeline MIT, web UI AGPL-3.0), dataset on Hugging Face (MIT; third-party data keeps its own terms).
Records: benchmark-radar.org records badge, Nov 17, 2026. Stars: GitHub, 409 on Nov 17, 2026. Sources: Nov 13, 2026.
Reach

Who is viewing or using it

  • Researchers at OpenAI, Anthropic, Google, Meta, Microsoft, NVIDIA, Amazon, IBM, ByteDance, and Unitree viewed/using it.
  • 300+ users across labs, companies, and universities.
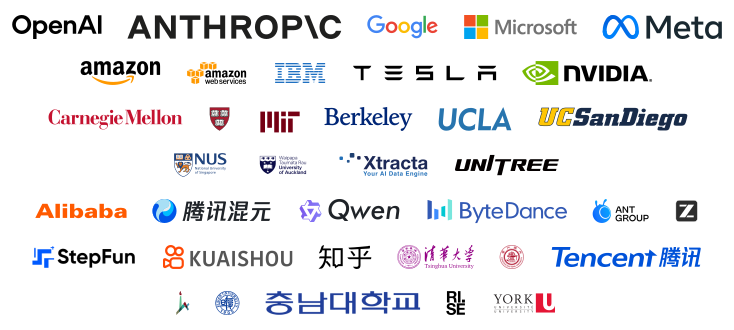
Logos of 37 institutions whose researchers viewed/using Benchmark Radar
The pipeline

How it works

  1. DiscoverNew benchmarks are found as they appear in papers, repos, datasets, and leaderboards.
  2. ExtractEach record keeps its original source, the reported score, who reported it, and the date.
  3. TrackScore history is followed over time, so new results and new versions stay visible.
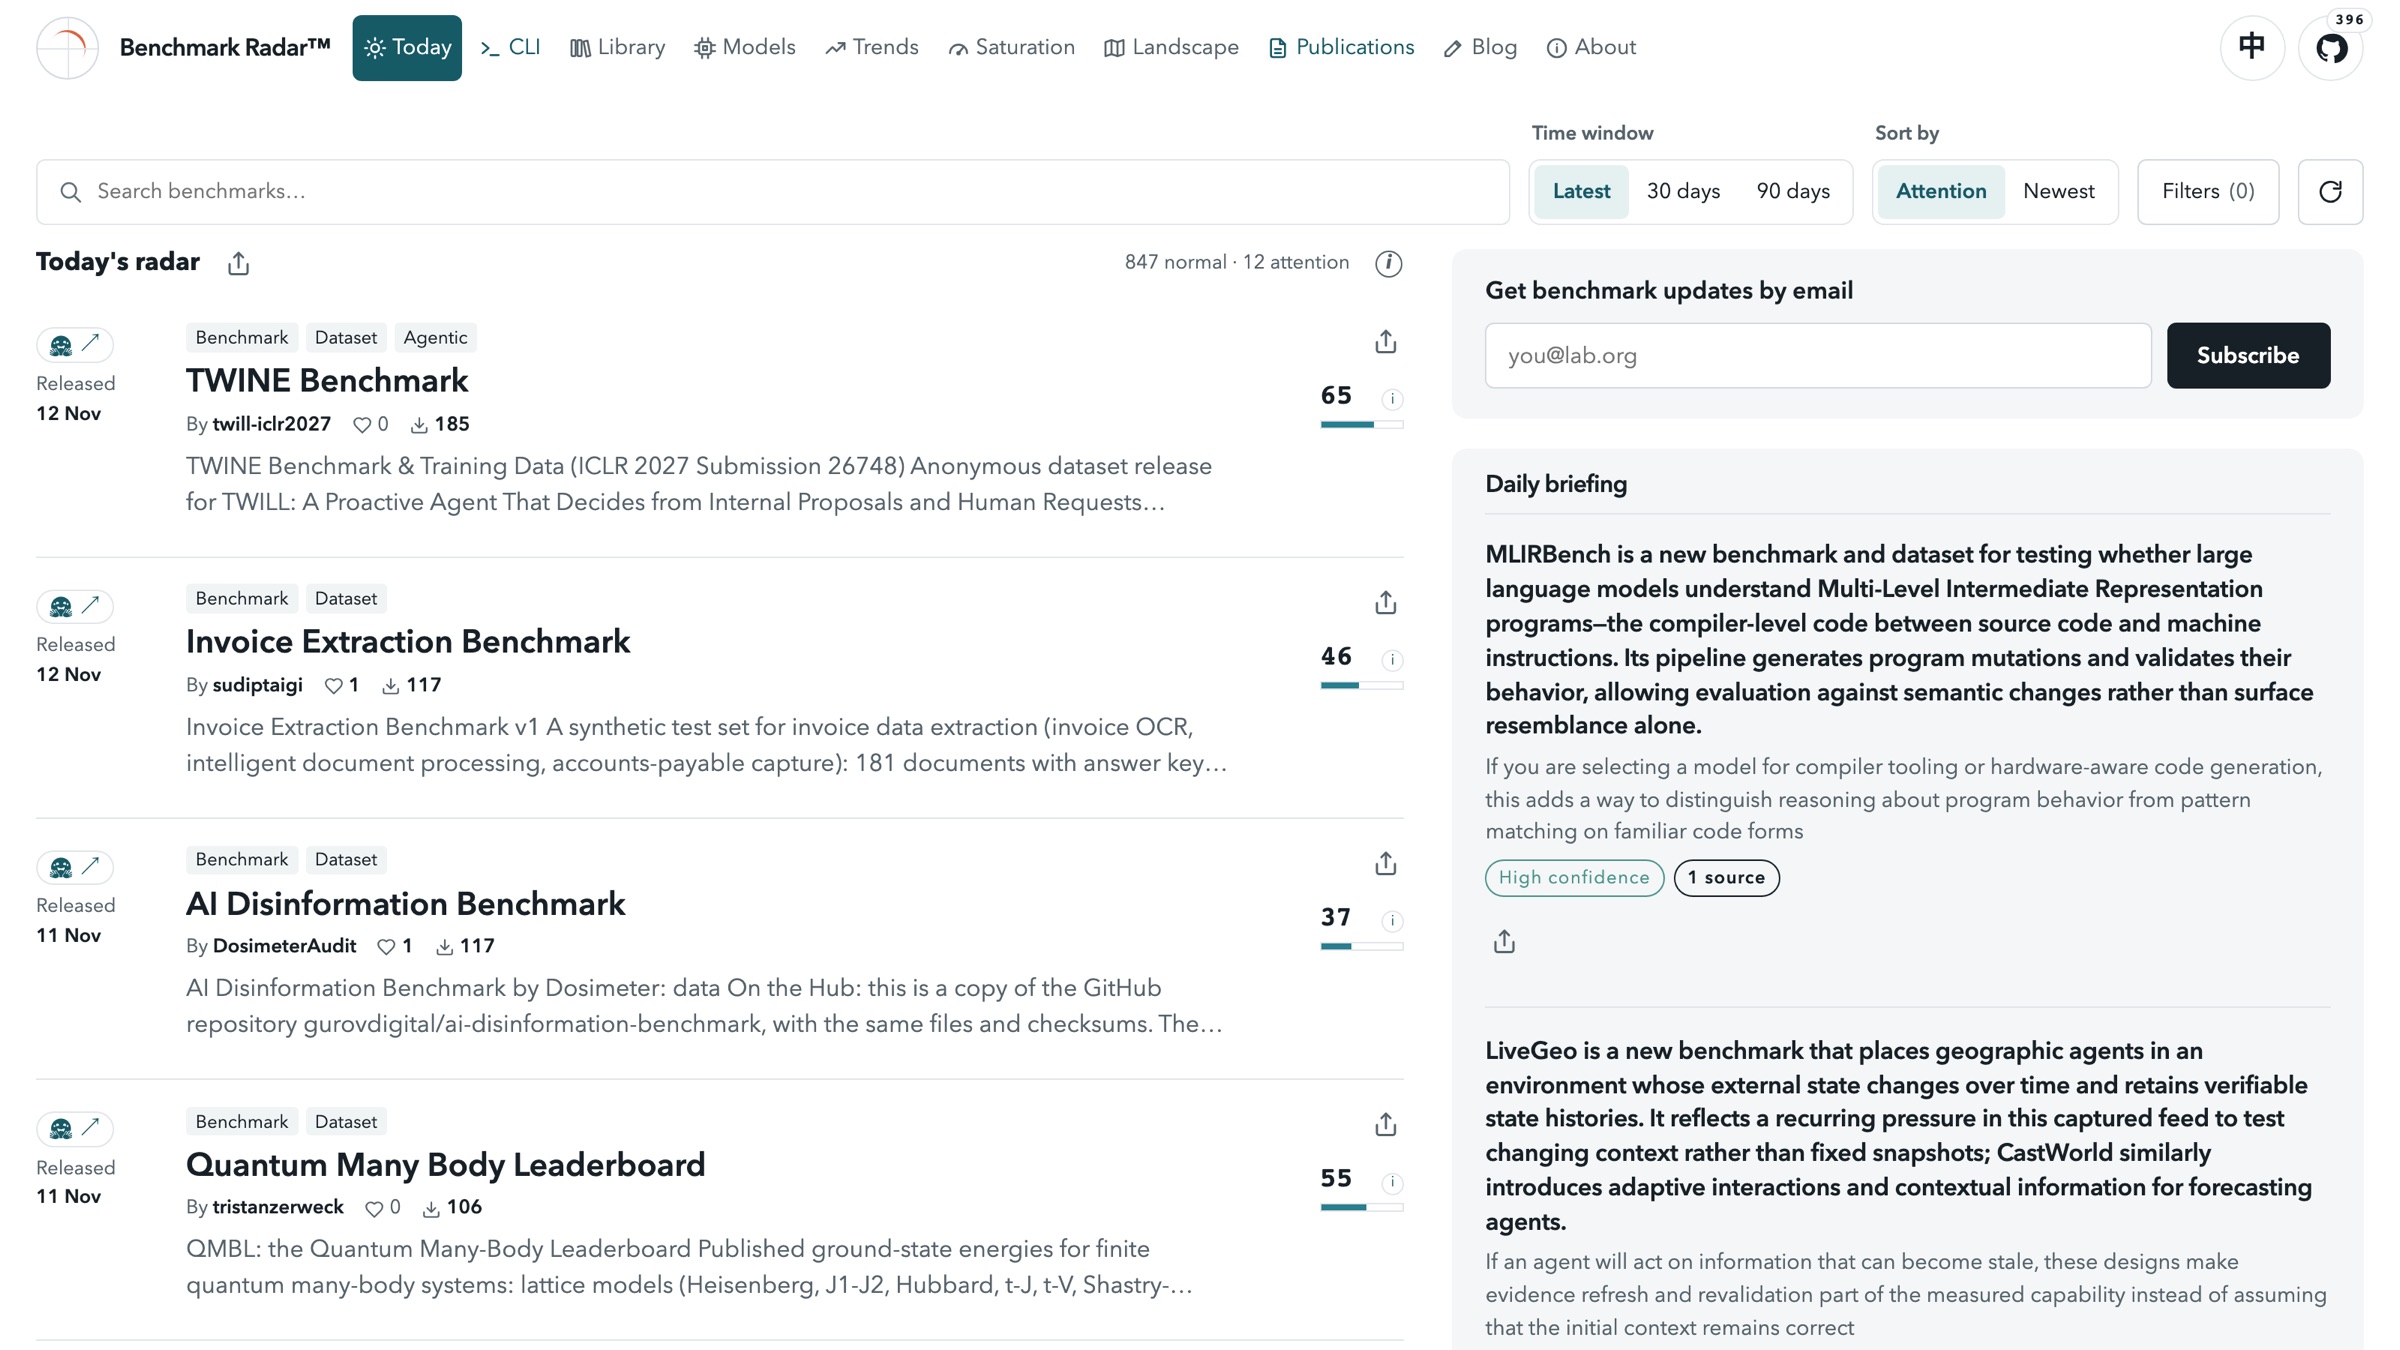
Benchmark Radar homepage: search bar, ranked new benchmarks, daily briefing
The live site: search at the top, today's new benchmarks ranked below, each linked to its source.
Finding 1 of 5

Attention

Repos with zero GitHub stars70%
Stars held by the top 1% of repos78%
Stars held by the top 10% of repos98%
1,024 GitHub repos behind 2,940 new benchmark releases from the last 90 days. Attention is a power law: a handful of benchmarks get almost all of it.
Stars measure attention, not quality. The benchmark your product needs may be in the 70%.
Benchmark Radar insights #1130, #1132; re-run Nov 13, 2026 on the 90-day window.
Finding 2 of 5

Papers

8.5★ vs 0★
median stars, repos with an arXiv paper vs without
21 of 29
repos with 100+ stars have a paper
14%
of repos in the cohort have a paper
  • This is an association, not a cause. A paper and stars can both come from a well-resourced team.
  • For your team: a paper-less benchmark is not wrong, but its setup is harder to check.
Benchmark Radar insight #1131; re-run Nov 13, 2026 (146 paper repos, 878 without).
Finding 3 of 5

Abandoned repos

35%
never pushed again after the day they were created (363 of 1,024)
5.3%
of repos are gone or made private: GitHub returns 404 (57 of 1,081)
  • A finished benchmark can be pushed once. One-day repos measure activity, not quality.
  • A missing repo is a dead citation. Radar now lists gone and archived repos without ranking them.
Benchmark Radar insights #1130, #1133. Gone = 404 on the GitHub repository endpoint, which follows renames.
Finding 4 of 5

Saturation

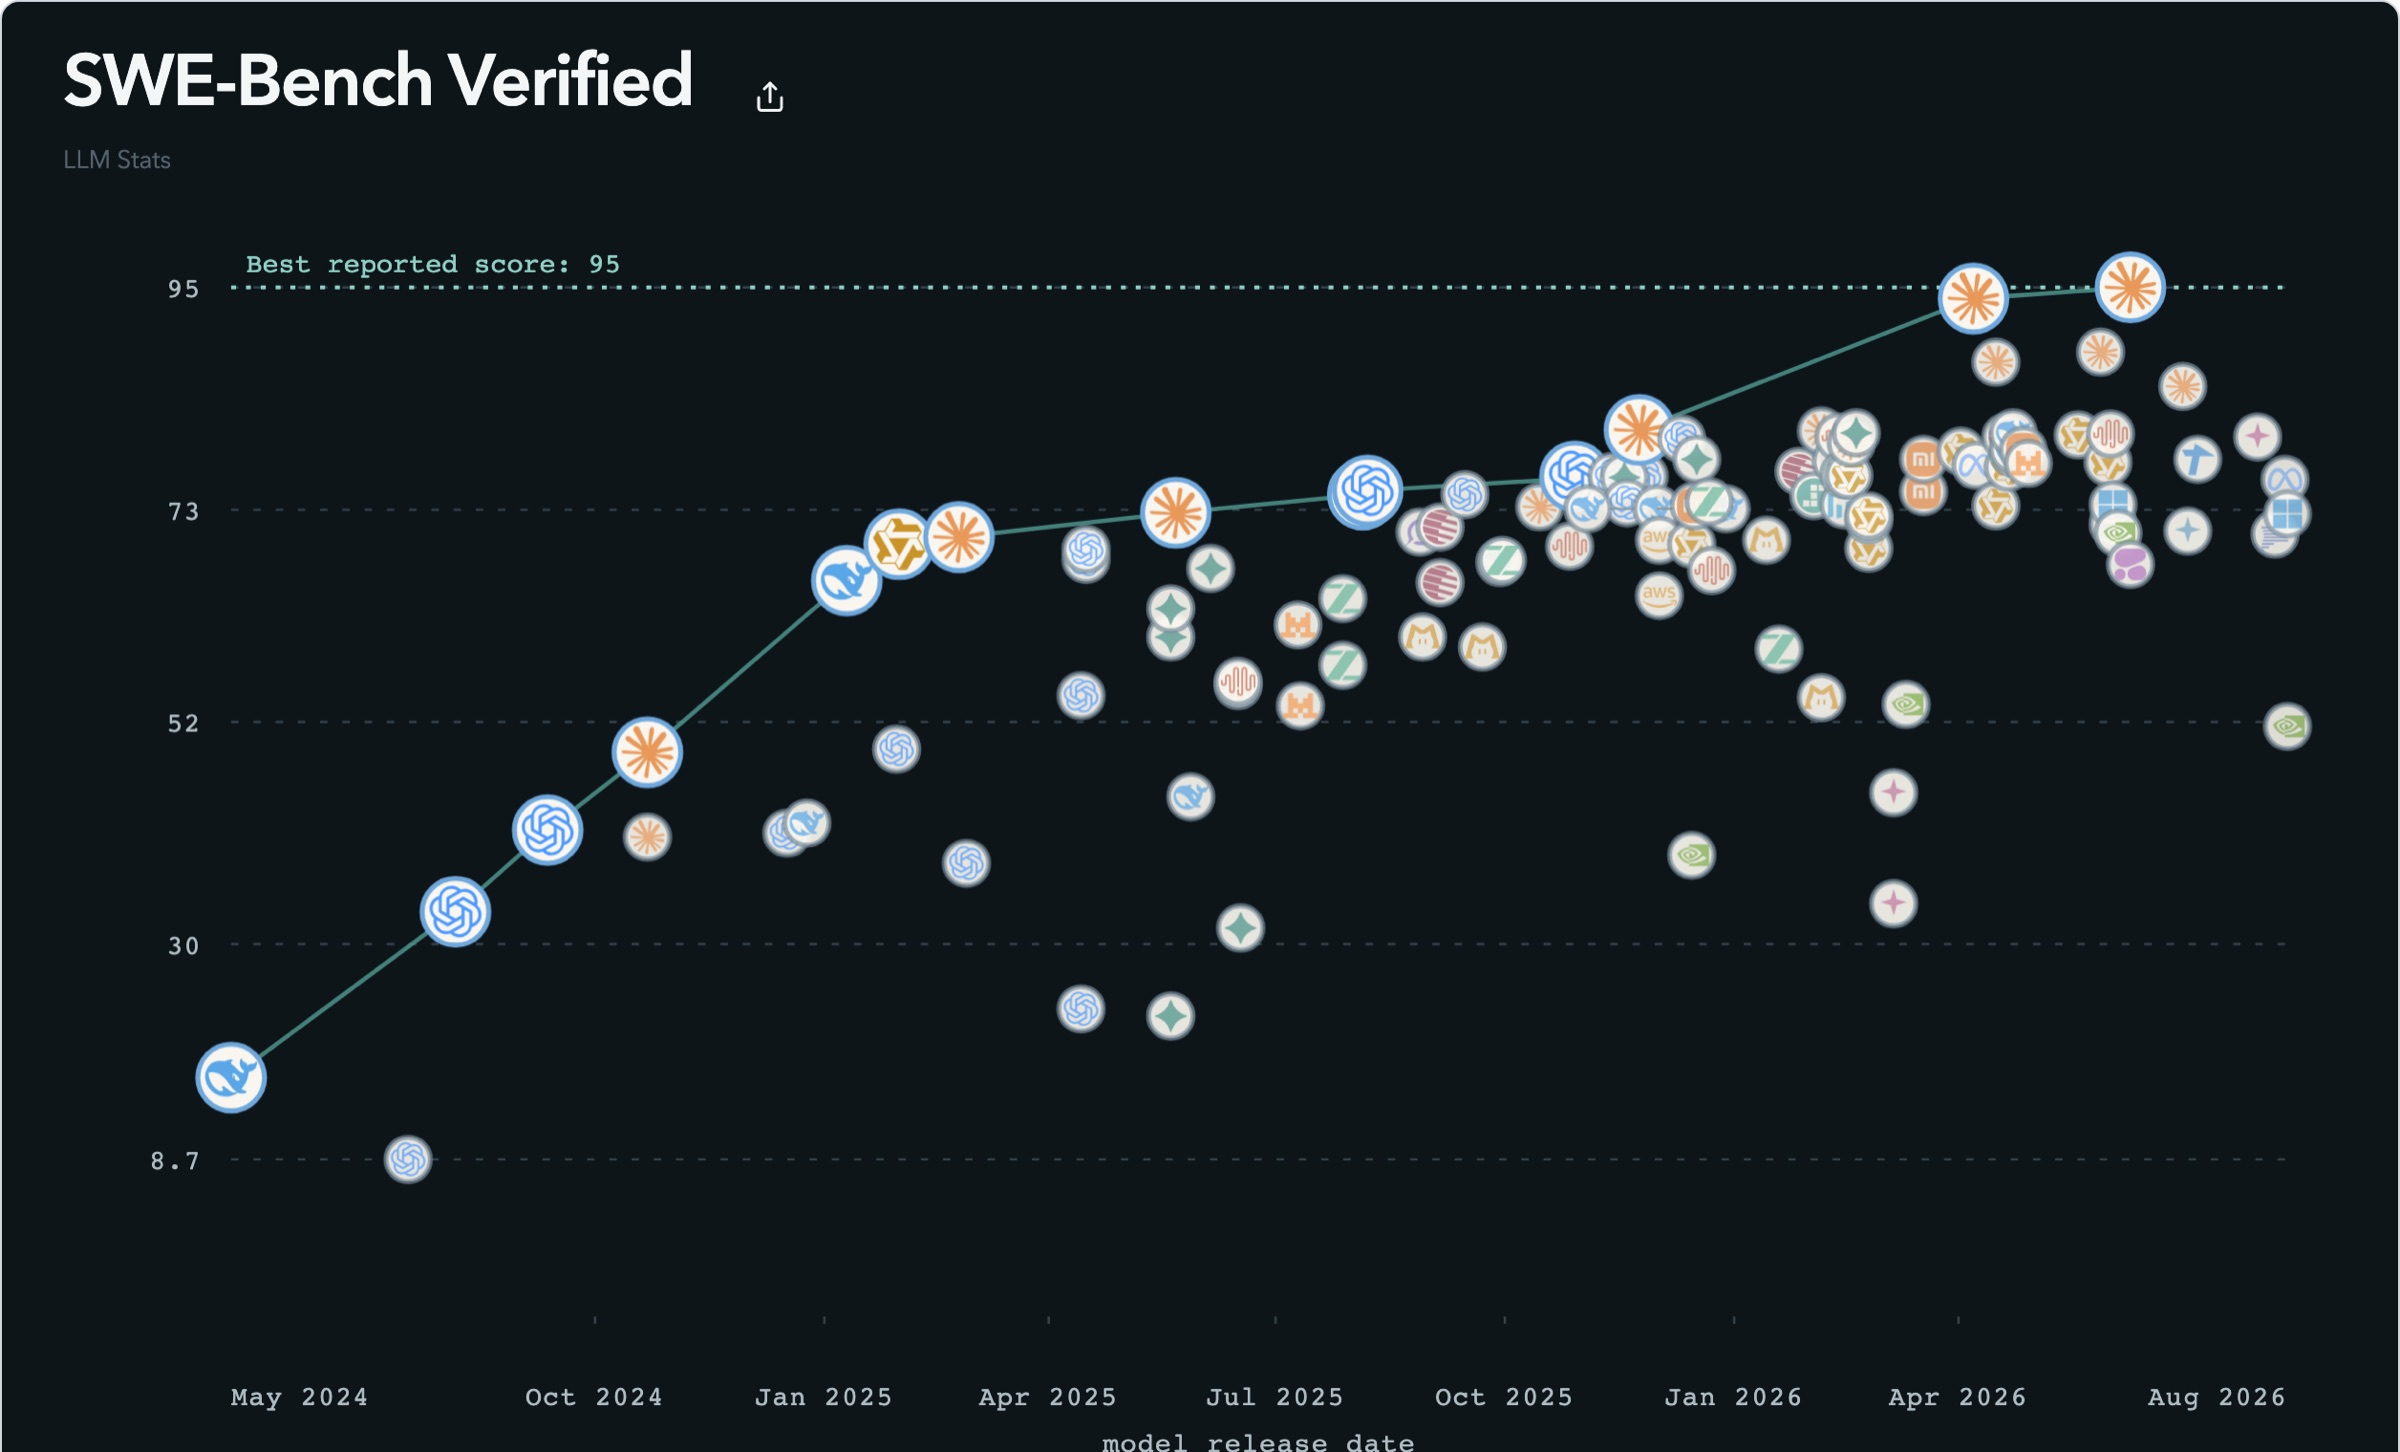
16.8 → 95.0
best reported SWE-bench Verified score, May 2024 → June 2026
65 of 111
reported scores are 70 or higher
Saturated is not solved. A crowded top means the test separates fewer models, not that the task is done.
SWE-Bench Verified score history on LLM Stats, 111 reported scores, best 95
SWE-Bench Verified, LLM Stats leaderboard, Benchmark Radar Saturation page, Nov 13, 2026.
Finding 5 of 5

Audits

SWE-bench Pro

109 of 728

public tasks underdetermined (15.0% floor); 3 gold patches fail the benchmark's own verifier.

Published June 21, 2026: 17 days before OpenAI's audit (July 8) estimated ~30% of tasks broken.

Terminal-Bench 2.1

40 of 83

gold-passing tasks still pass after a careless in-workspace deletion.

DeepSWE

4 of 113

reference solutions fail their own verifiers (v1.0). The v1.1 re-grade fixed 3 of them.

  • Radar lists 9 audits of 8 benchmarks, all by June Kim: also ProgramBench, MirrorCode, FrontierCode, SlopCodeBench, and Frontier-Bench.
Findings as reported by each audit, linked from the benchmark's Radar record (june.kim, GitHub, Zenodo).
Take home

A five-step check

01 · Finding 1

Discover wide

Start from the full landscape, not from what is trending.

02 · Findings 2–3

Check provenance

Find the paper, the repo, and who reported each score. Confirm the repo still exists.

03 · Finding 4

Check saturation

Ask whether it still separates your candidate models.

04 · Finding 5

Check audits

Look for an independent recheck before you rely on it.

05

Schedule retirement

Decide in advance when the eval gets dropped, and write the date down.

Roadmap

What is next

  • Wider coverage. More sources, more benchmarks, and faster pickup of new releases.
  • A deeper audit layer. More audit records linked to the scores they examine.
  • Interop with community efforts. Radar's records should flow into shared efforts such as Every Eval Ever, not sit in a silo.
  • Better history views. Score movement over time, readable at a glance.
For your paper

Let your agent draft Related Work

  • Install once.One command adds the Benchmark Radar Skill to your coding agent.
  • Name your themes.Ask your agent for a Related Work section, one paragraph per theme.
  • Get LaTeX and BibTeX.A cited Related Work draft and the missing BibTeX entries, ready to edit.
$ npx skills add ktwu01/benchmark-radar --skill benchmark-radar
For your benchmark

Search for it. If it is missing, add it.

  • Search.52,120 benchmark records from 41 public sources, one search box.
  • Not there?Open the “Submit a benchmark” form on GitHub. English or Chinese is fine.
  • Help the next team.Every benchmark you add is one more that others can find.
benchmark-radar.org
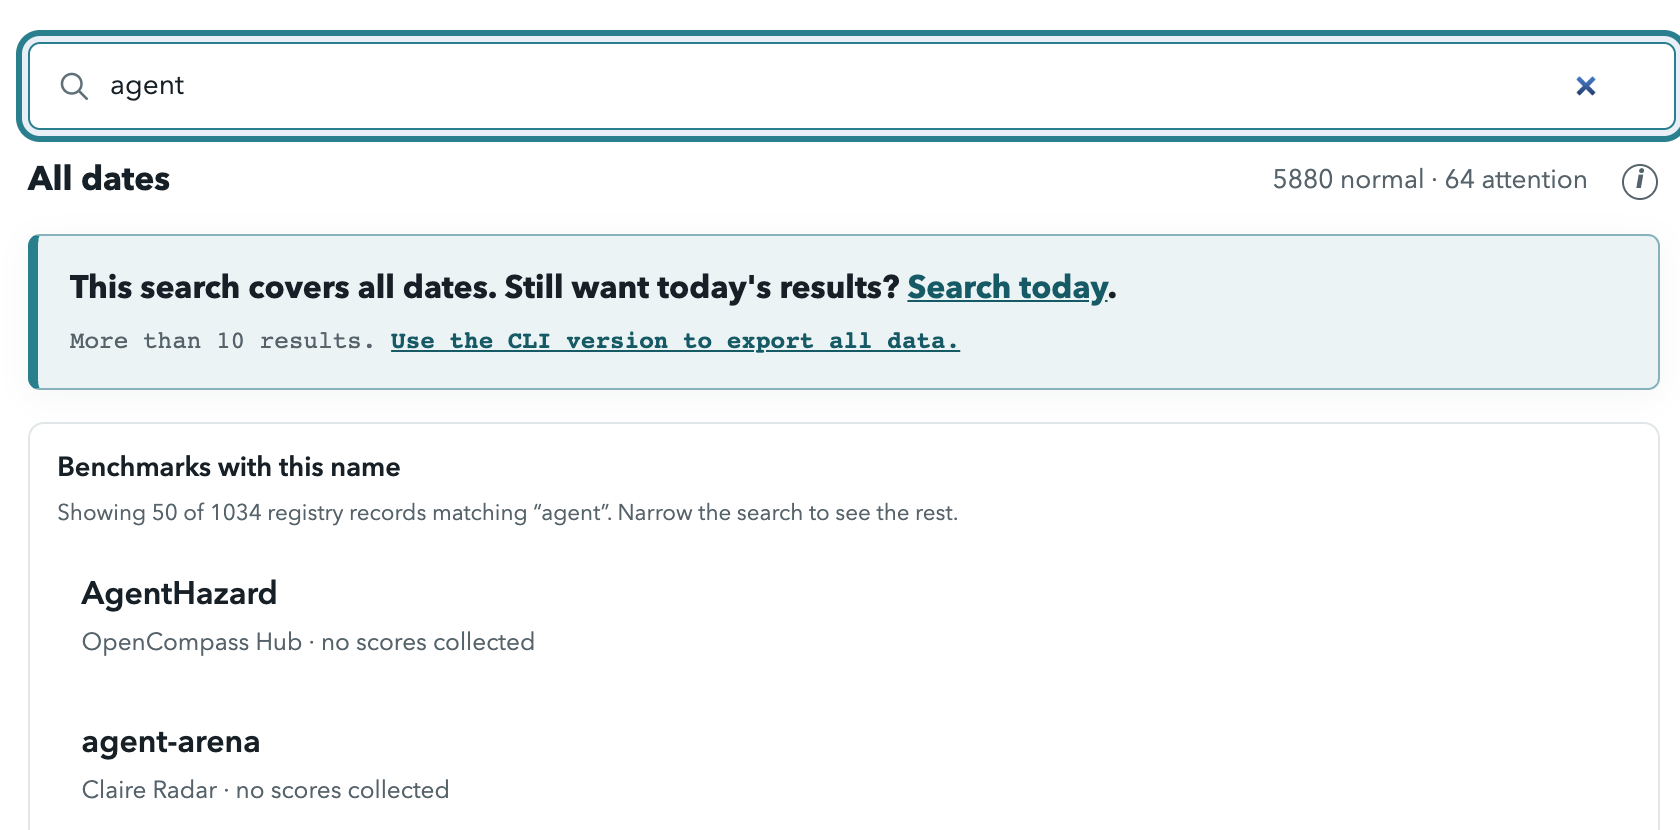
Benchmark Radar search for “agent”, showing 1,034 matching benchmark records
For your inbox

Get new benchmarks by email

  • Open the homepage.The signup box sits next to the search results.
  • Pick daily or weekly.Daily brings the latest each day; weekly arrives every Monday.
  • Leave anytime.Every email has an unsubscribe link.
  • No email needed.The same Daily briefing is on the homepage.
benchmark-radar.org
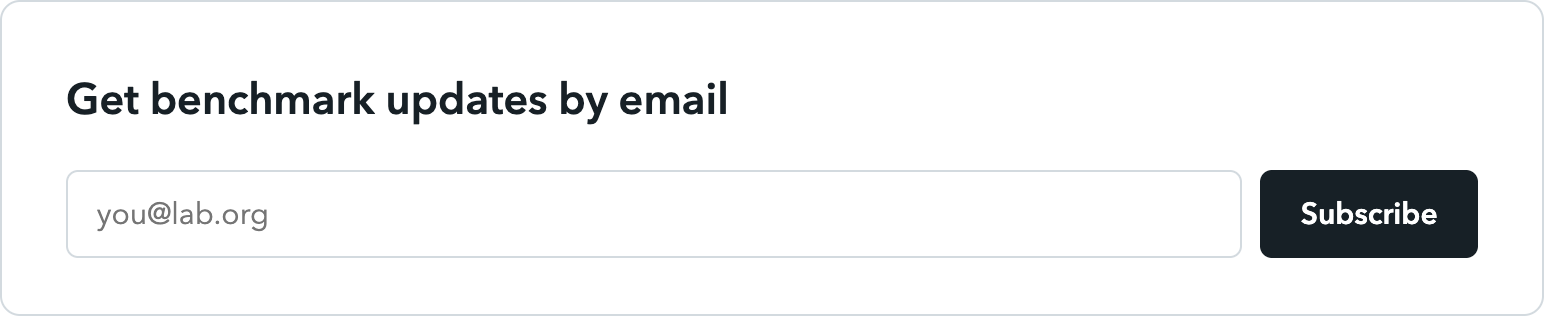
Email signup box on the benchmark-radar.org homepage: Get benchmark updates by email, an email field, and a Subscribe button
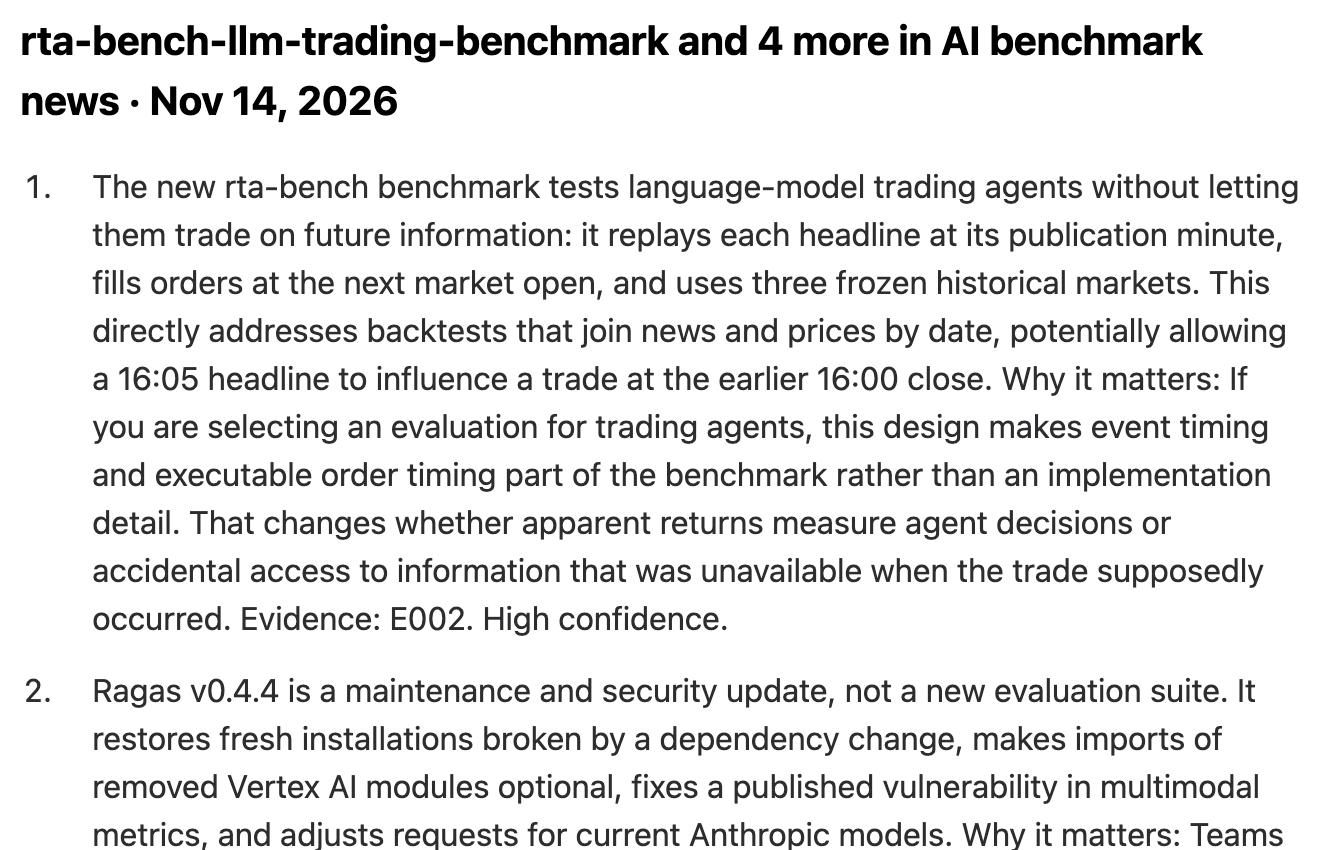
The Benchmark Radar daily brief email for Nov 14, 2026: numbered summaries of rta-bench and Ragas v0.4.4, each with why it matters, evidence, and confidence
Join in

Get involved

  • Use the dataset. The full record set is open: huggingface.co/datasets/ktwu01/benchmark-radar
  • Contribute a benchmark. If Radar missed one you care about, adding it is a small issue.
  • Report an error. A wrong score or a missing source is worth a flag.
  • Publish an audit. Radar links it next to the scores it examines.
  • Start at benchmark-radar.org. Code and issues: github.com/ktwu01/benchmark-radar
QR code to join the Benchmark Radar DiscordDiscord: Benchmark Radar
QR code to add Koutian Wu on WeChatWeChat: Koutian Wu
Thank you

Acknowledgments

June Kim

Independent audits of SWE-bench Pro, Terminal-Bench 2.1, DeepSWE, and five more benchmarks: the evidence behind Finding 5.

Prahitha Movva and Cohere Labs

For hosting this talk in the Open Science Community.

Q&A

Questions

Which eval does your team trust most, and when did you last check it?
I am looking for my next role in AI evaluation, starting Feb '27. If your team is hiring, or you can refer me, please email me: ktwu@utexas.edu
QR code to join the Benchmark Radar DiscordDiscord
QR code to add Koutian Wu on WeChatWeChat
← All talks